
Zyphra addresses the growing demand for high-quality, customizable synthetic speech with advanced text-to-speech (TTS) and voice cloning capabilities. Its Zonos-v0.1 models provide expressive audio generation, making it a valuable tool for various digital content needs.
Zonos: Open-Source TTS with Emotion and Pace Control
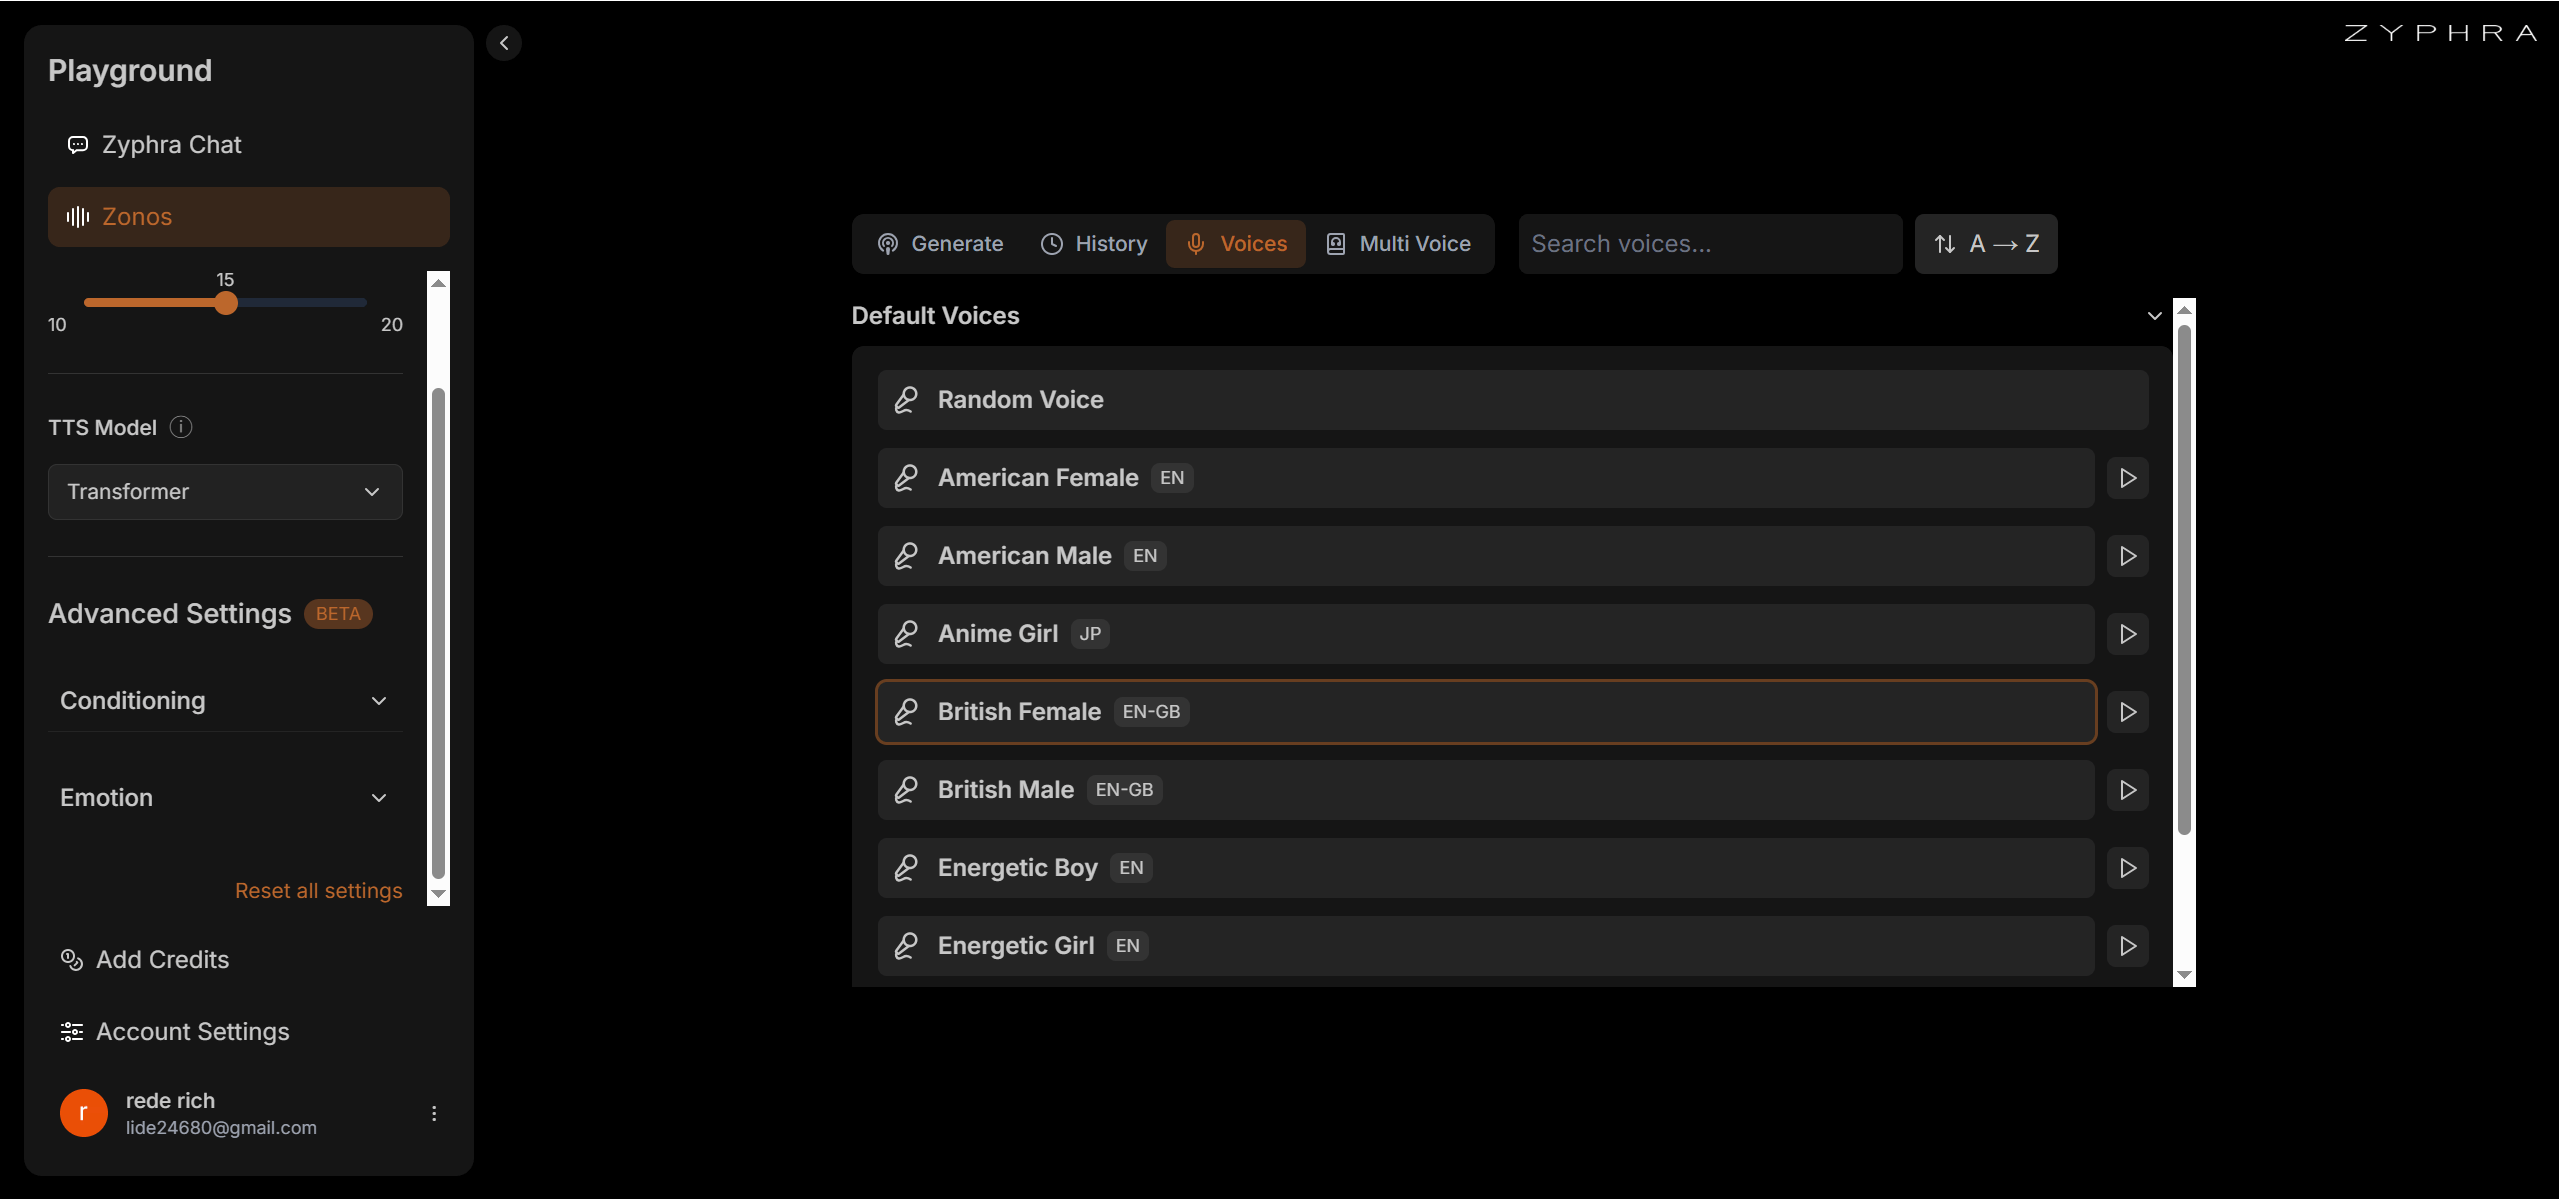
At its core, Zyphra utilizes the Zonos-v0.1 suite of text-to-speech models. These models excel at generating natural and expressive speech from text inputs. A key feature is high-fidelity voice cloning, which requires only short audio clips, typically between 5 to 30 seconds. Users gain fine-grained control over speech modulation, including rate, pitch, quality, and emotions like sadness, happiness, and anger.
Voice AI Researchers, TTS Developers, and Audio Engineers
Zyphra serves several user groups, including content creators, developers, and businesses. Its applications span various use cases:
- Audiobooks: Automating voice synthesis for narrative content.
- Virtual Assistants: Providing natural-sounding voices for interactive systems.
- Content Localization: Adapting audio content for different linguistic markets.
- Marketing Agencies: Creating compelling voiceovers for campaigns.
- Educational Institutions: Developing engaging learning materials.
Zyphra also serves startups, entrepreneurs, and product managers for tasks like brainstorming and project management, using its broader AI research and cloud services.
Apache 2.0, Fast Inference, Speaker Conditioning
Zyphra’s Zonos-v0.1 models, which include both transformer and hybrid architectures, are trained on approximately 200,000 hours of varied multilingual speech data. They deliver speech at a native resolution of 44KHz. The models are available on Hugging Face and GitHub under an Apache 2.0 license, promoting broad use and community development. Zyphra also provides API and model playground integration support for Python and TypeScript.
Supported output audio formats include WebM, Ogg, WAV, MP3, and MP4/AAC, offering flexibility for diverse platforms. While primarily supporting English, the models also have substantial datasets for Chinese, Japanese, French, Spanish, and German.
Open-Source (Free), Cloud API Available
Zyphra offers several pricing tiers to accommodate different usage levels:
| Plan | Price | Key Details |
|---|---|---|
| Free | Free | 100 minutes per month |
| Pro | $5/month | 300 minutes per month |
| Pay-as-you-go | $0.02/minute | Per-minute usage |
Custom enterprise tiers are also available for unlimited voice cloning and concurrent generations.
Emotion Tags, Speaking Rate Control, and Accent Adjustment
Zyphra’s Zonos models provide a notable advantage through their fine-grained control over emotions, speaking rate, pitch, and audio quality, often exceeding alternatives in this regard. The Apache 2.0 license for Zonos-v0.1 models encourages broad adoption and community contributions. Zyphra also focuses on developing efficient, small, yet powerful language models optimized for consumer and edge devices, aiming to democratize AI access. Its ZAYA1-8B reasoning model, for instance, achieves performance comparable to much larger models with significantly fewer active parameters, enhancing inference efficiency.
English-Focused, Still Early-Stage Model
Zyphra’s tools have beta-phase limitations:
- As a beta product, expect occasional bugs, incomplete features, and potential API changes without notice.
- Voice cloning quality depends heavily on the quality and length of the reference audio sample provided.
- Limited language support compared to more established TTS platforms.