

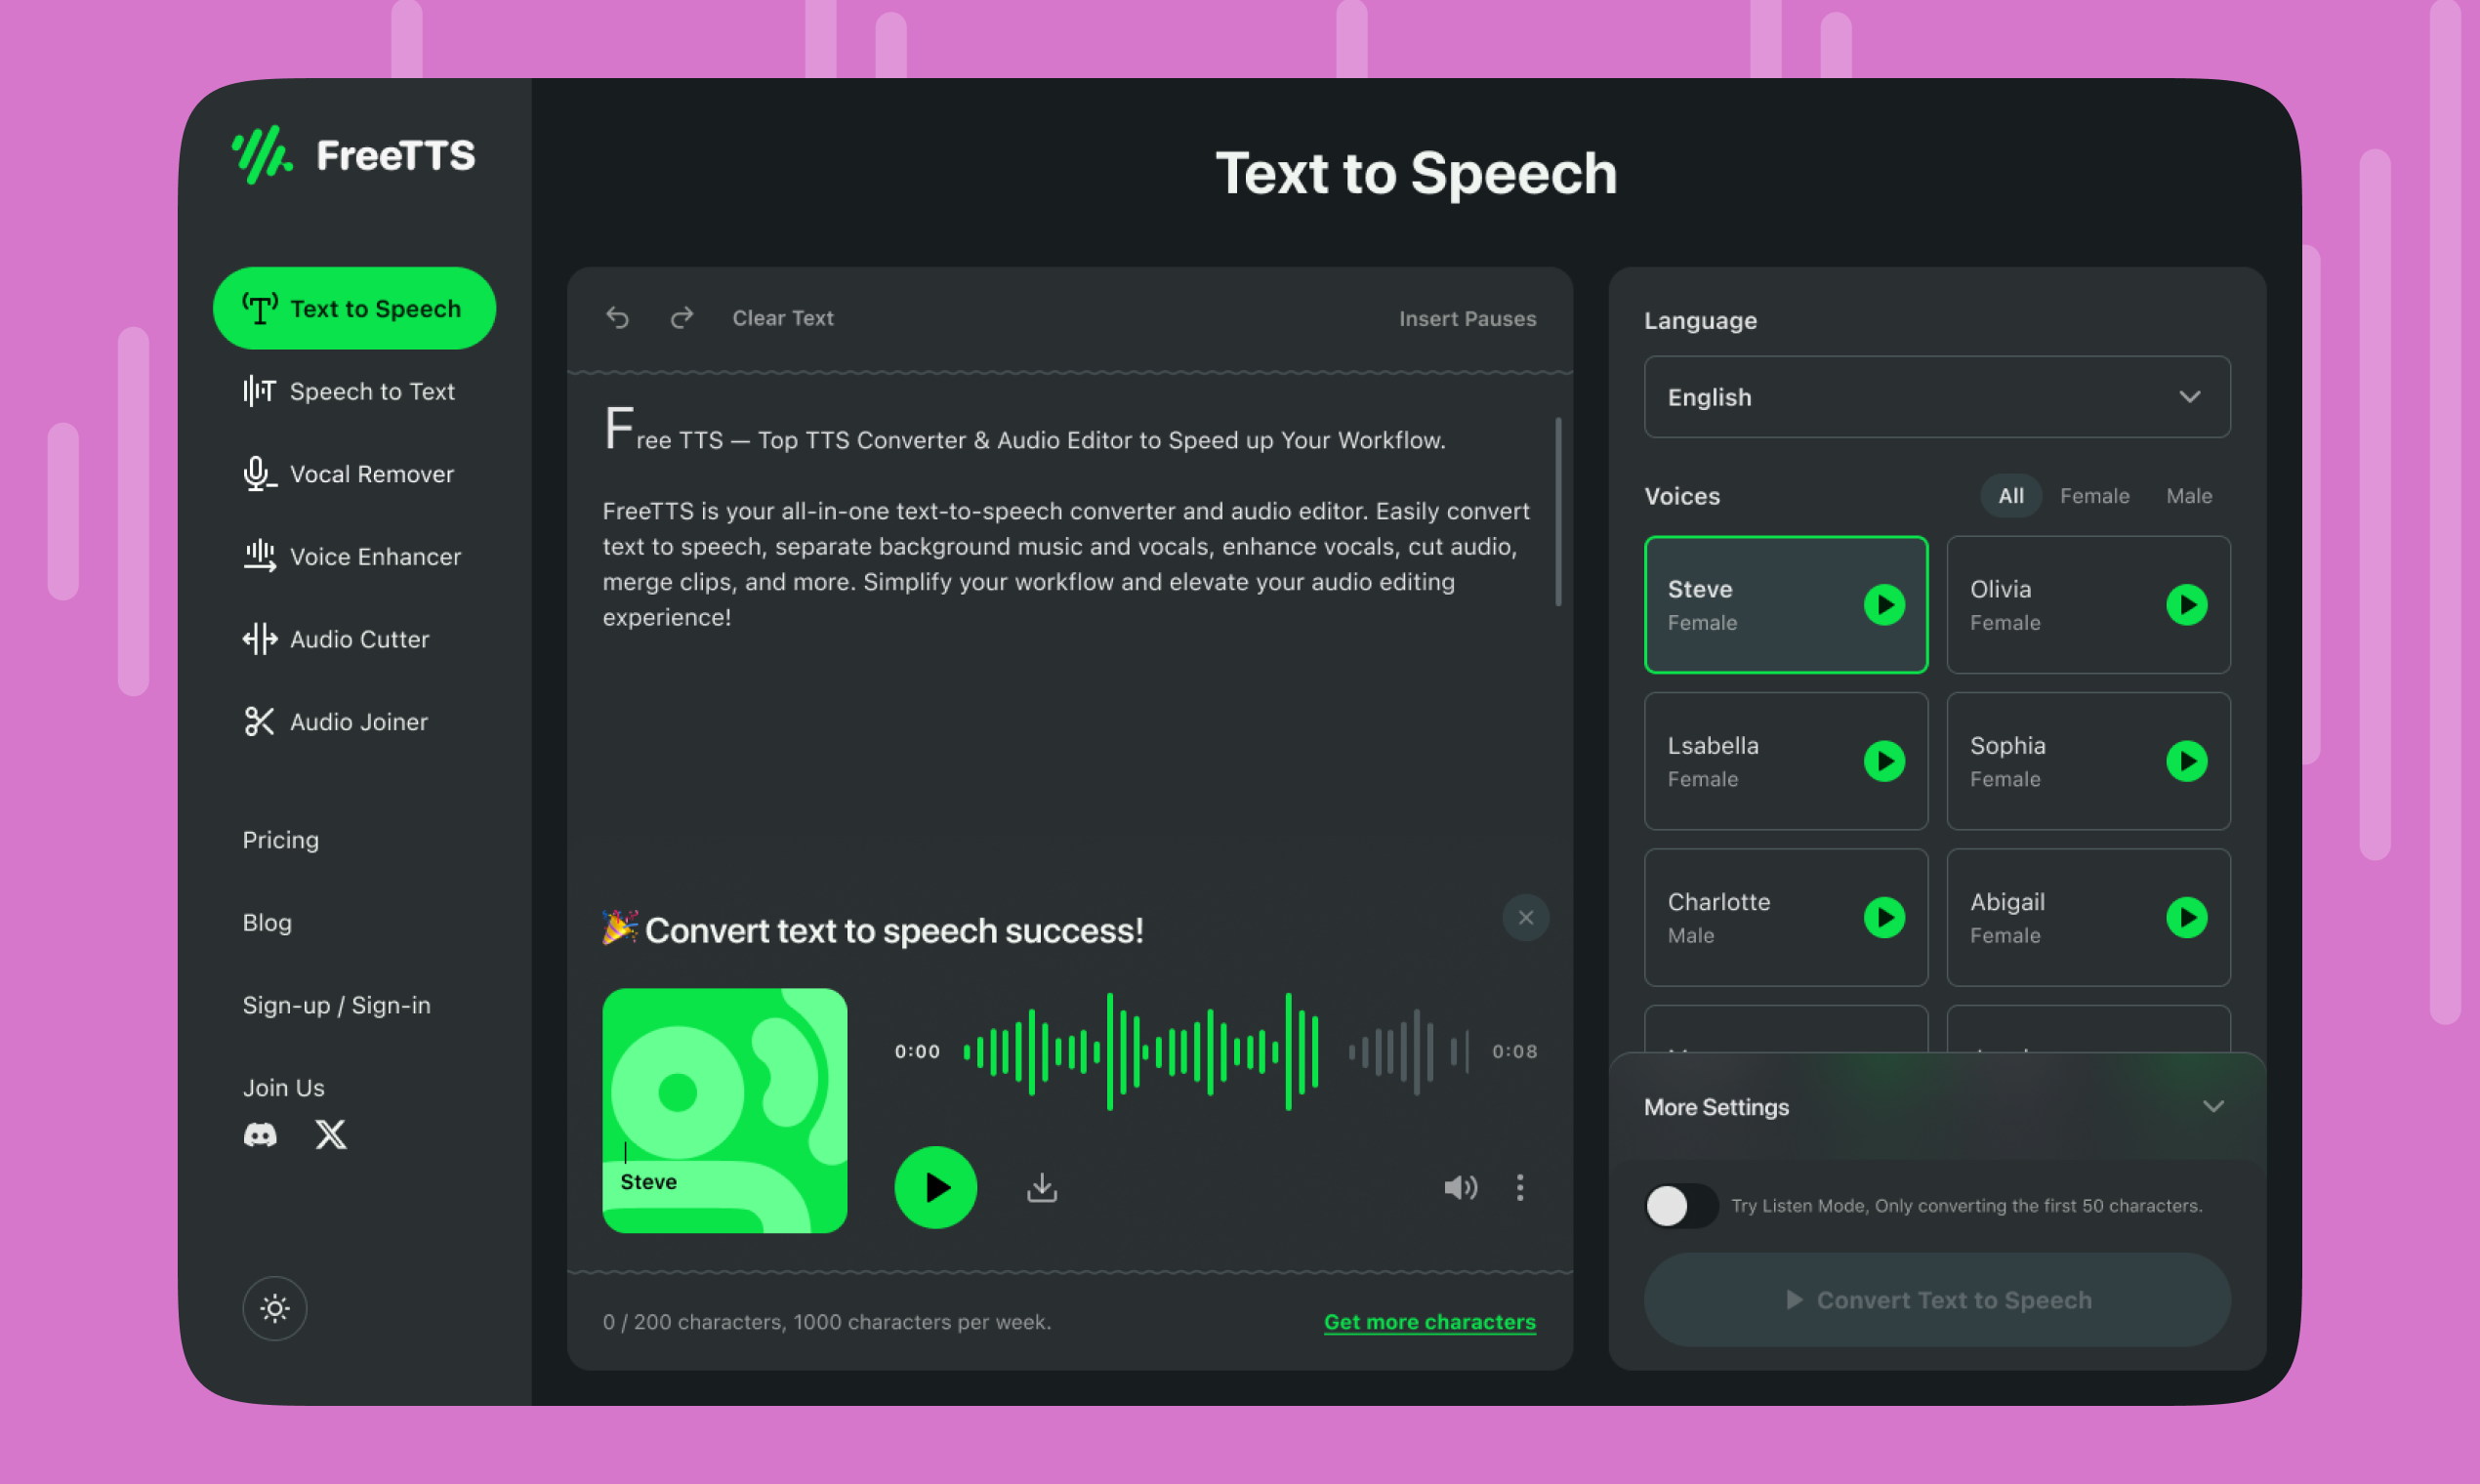
Producing natural-sounding audio from text can be a bottleneck for many content creators and developers. FreeTTS addresses this by offering an online platform that transforms written content into speech, alongside a suite of other audio utilities.
FreeTTS: Free Online Text-to-Speech Aggregator
FreeTTS is primarily a text-to-speech (TTS) converter, leveraging neural AI voices to create high-quality, natural-sounding audio. Beyond its core TTS function, the platform integrates several other audio tools:
- Speech-to-Text Transcription: Converts spoken audio into written text.
- Vocal Removal: Separates vocal tracks from instrumental music.
- Voice Enhancement: Improves the quality of recorded speech.
- Audio Editing: Includes tools for converting audio formats, compressing files, cutting segments, and joining multiple audio files.
Users can input text, choose from a wide selection of voices, and download the resulting audio as an MP3 file. It further generates synchronized SRT subtitle files, useful for video content.
Casual Users, Quick Voiceovers, and TTS Comparison
FreeTTS serves a diverse user base, making it a versatile tool for various applications:
- Content Creators: Ideal for YouTube narration, Instagram reels, TikTok voiceovers, and podcasts, especially for channels that require consistent, professional audio without hiring voice actors.
- Educators and E-learning Creators: Useful for developing audio textbooks, voiceovers for training modules, tutorials, and presentations. It also aids in proofreading written work by listening to it aloud.
- Accessibility Users: Provides an accessible way for individuals with visual impairments, dyslexia, or reading difficulties to consume written content audibly.
- Developers: Offers a free REST API for prototyping voice features in applications, avoiding upfront costs for expensive API contracts.
- Language Learners: Helps with pronunciation by allowing users to hear text spoken in various languages.
- Professionals: Converts long reports and emails into audio for consumption during commutes or for proofreading important documents.
- Small Businesses and Freelancers: Accelerates content production and improves productivity by reducing reliance on external voiceover services.
Google/Amazon/Microsoft Voices, MP3 Download, No Login
FreeTTS utilizes advanced machine learning and AI from Google and Amazon to power its features. It boasts over 400 neural AI voices across 75+ languages. Paid plans unlock 95 expressive voice styles.
- Output Formats: Generates MP3 audio files and synchronized SRT subtitle files. PRO plans add WAV and OGG export options.
- Character Limits: The free tier allows 1,000 characters per generation and 5,000 characters per month. PRO plans increase this to 10,000 characters per generation and 1,000,000 characters monthly, while Creator plans offer 25,000 characters per generation.
- API Access: A free REST API is available without a key, supporting 15 requests per minute on the free tier. PRO plans allow 200 requests per minute, and Creator plans support 1,000.
- SSML Support: Full W3C SSML (Speech Synthesis Markup Language) specification support enables precise control over speech patterns, including phoneme tags, prosody, break tags, and emphasis.
- Integrations: Compatible with video editing software like YouTube Studio, Premiere Pro, DaVinci Resolve, and CapCut, as well as any platform that accepts .srt files.
- Privacy: The platform claims a privacy-first approach, clearing uploaded files and results within 12-24 hours.
Free with Ads and Limits, Premium for Ad-Free
FreeTTS operates on a freemium model, offering various plans to suit different needs:
| Plan | Price | Key Details |
|---|---|---|
| Free Tier | Free | 5,000 chars/month (1,000 chars/gen), 400+ voices, 75+ languages, MP3 download with audio watermark, personal use only, no credit card/signup required |
| PRO Plan | $19/month or $149/year or $199 one-time | 1,000,000 chars/month (10,000 chars/gen), 95 expressive voice styles, HD voices, WAV export, commercial license, no watermark, 200 API requests/min |
| Creator Plan | $39/month | 25,000 chars/gen, commercial licenses for YouTube, podcasts, courses, client work, voice cloning |
Some sources also mention Starter ($9.90/month for 460,000 chars) and Premium ($19.90/month for 950,000 chars) plans, which include ASR Speech to Text hours and an ad-free experience.
Low Audio Quality, No Batch Processing, Usage Caps
While FreeTTS offers a strong set of features, users should be aware of certain limitations:
- Free Tier Constraints: The free tier imposes character limits, includes an audio watermark, and is restricted to personal use. Commercial projects require a paid subscription.
- Voice Customization: Although paid plans offer expressive styles, the free plan’s standard voices may lack the emotional depth and advanced customization found in more premium, dedicated voice synthesis tools. Voice cloning is exclusive to the Creator plan.
- Input Method: The web-based tool primarily supports copy-pasting text. Direct file import for documents like PDFs or DOCX isn’t available.
- Internet Dependency: As a web-based platform, a stable internet connection is necessary for all operations. there’s no dedicated mobile app or full-featured desktop application.
- Technical Glitches: Some user feedback indicates occasional technical issues, such as conversion failures or download errors, even with paid plans. Users should verify reliability for critical workflows.
Fastest Free TTS Without Account Creation
FreeTTS stands out for its accessible and relatively generous free text-to-speech service compared to many competitors, which often have stricter character limits or require account creation for basic use. Its ability to generate perfectly synced SRT subtitle files directly from the synthesis engine streamlines workflows for video creators. The full W3C SSML support provides developers and advanced users with precise control over speech output, a feature often limited in other free or lower-tier services. The availability of a free public API without a key is particularly appealing for developers looking to prototype voice features without initial investment. For quick, natural-sounding audio for personal projects, accessibility needs, or initial content creation, its ease of use and browser-based nature make it a strong contender.