

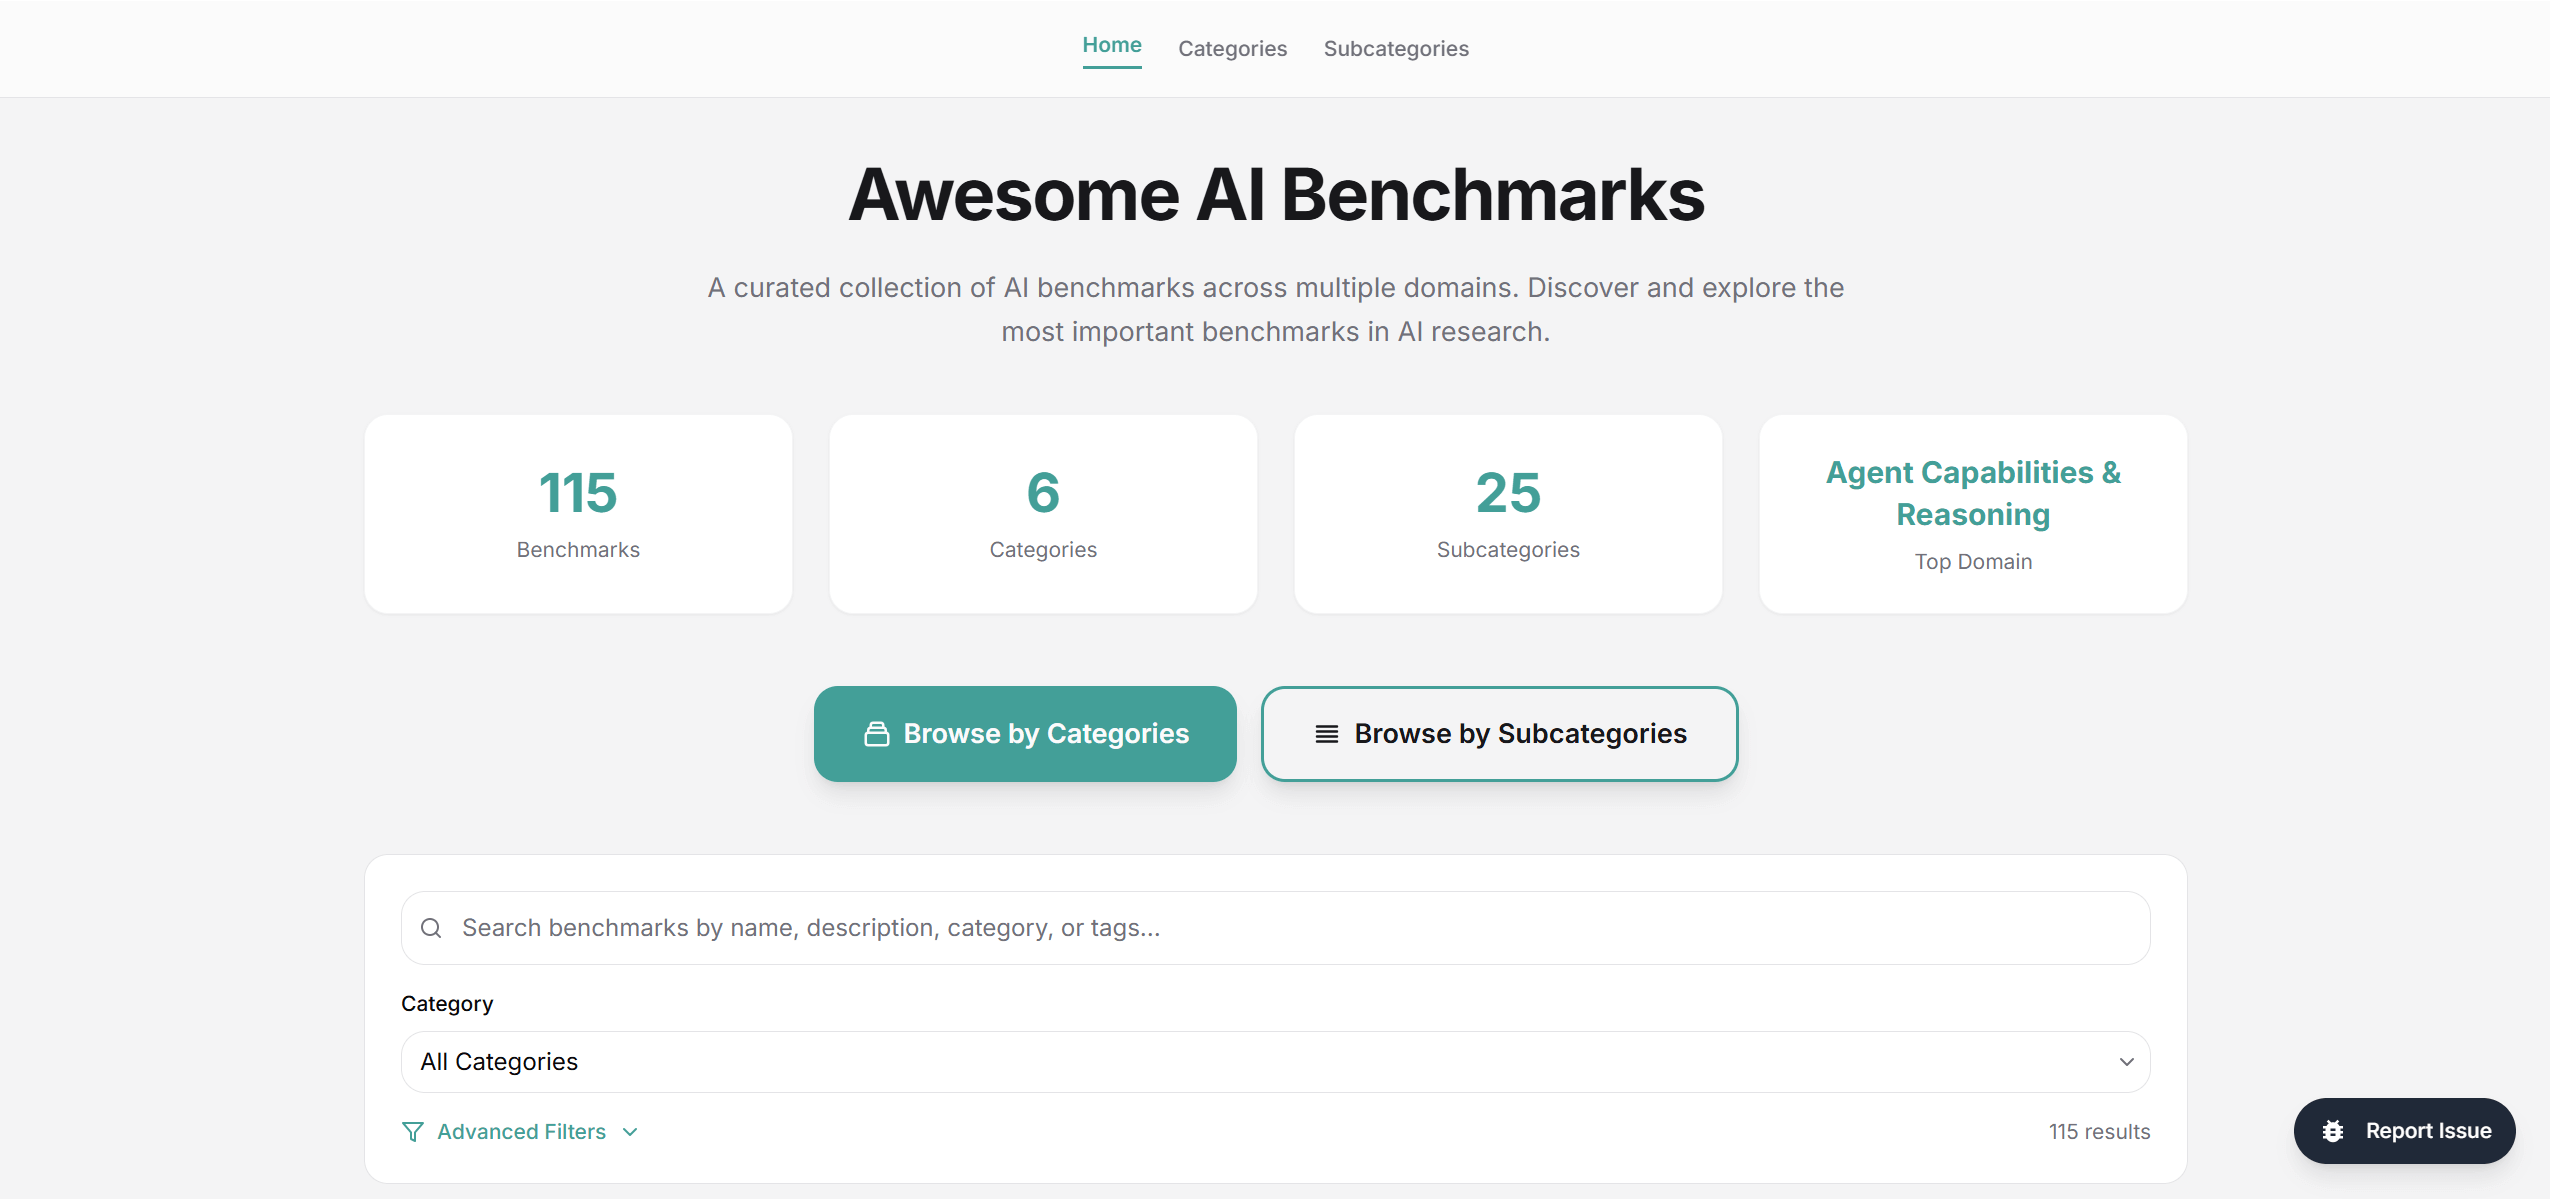
Selecting the right AI model for a specific task can be complex, with numerous options offering varying capabilities and costs. AIBenchmarks (aibenchmarks.net), closely associated with "Artificial Analysis," simplifies this by providing an independent platform to audit and compare the performance of over 200 AI models, particularly Large Language Models (LLMs).
Aggregated LLM Scores from MMLU, GSM8K, and HumanEval
The platform offers a curated collection of over 100 AI benchmarks across diverse domains, including agent capabilities, reasoning, code generation, and multimodal tasks. It provides independent analysis and comparison of AI models and API providers based on key performance metrics. Users can explore leaderboards, compare models side-by-side, and receive personalized recommendations tailored to their priorities for intelligence, speed, and cost.
CTOs, AI Engineers, and Technology Decision Makers
This tool reaches multiple user segments, including AI researchers, developers, engineering teams, product builders, and business operators. Specific use cases include:
- Informed AI Investments: Making data-driven decisions about where to allocate resources for AI integration.
- Optimal Model Selection: Identifying the most suitable AI models for tasks such as coding, scientific research, general work, or customer support.
- Understanding AI Evolution: Gaining insights into the evolving capabilities and limitations of various AI technologies.
Multi-Benchmark Normalization with Cost/Performance Overlay
AIBenchmarks supports a wide range of LLMs from major providers like OpenAI, Google, Anthropic, DeepSeek, and MiniMax. It benchmarks capabilities across natural language understanding, vision, math, coding, and agentic functions. Key metrics include:
- Intelligence Index: A composite score reflecting overall model intelligence.
- Output tokens per second: Measures the speed of model output.
- USD per 1M tokens: Provides real-world pricing for model usage.
For specific benchmarks, the platform tracks success rates, hallucination rates, time to first token, and tokens per second. The platform is powered by "Artificial Analysis & OpenRouter" and aggregates data from established benchmarks like GPQA Diamond, SWE-bench Verified, MMLU, and Terminal-Bench.
Free Web Dashboard
AIBenchmarks is described as a "Free AI Model Performance Auditing Tool." While the auditing tool itself is free to use, the underlying AI models being benchmarked may have associated costs, which the platform details (e.g., USD per 1M tokens). It tracks over 200 models, with more than 23 of these being free models.
Benchmarks Are Proxies, Not Production Guarantees
While AIBenchmarks provides valuable comparative data, it’s crucial to acknowledge the inherent limitations of AI benchmarking. Models can sometimes be "overfit" or "custom-tailored" to perform exceptionally well on specific benchmarks, which doesn’t always translate to equivalent real-world performance. Other concerns include benchmarks lacking diversity, aging quickly, potential construct validity problems, and the possibility of data contamination where training data includes benchmark datasets. Users should also consider the transparency of benchmark creation and potential biases from model developers when interpreting results.