
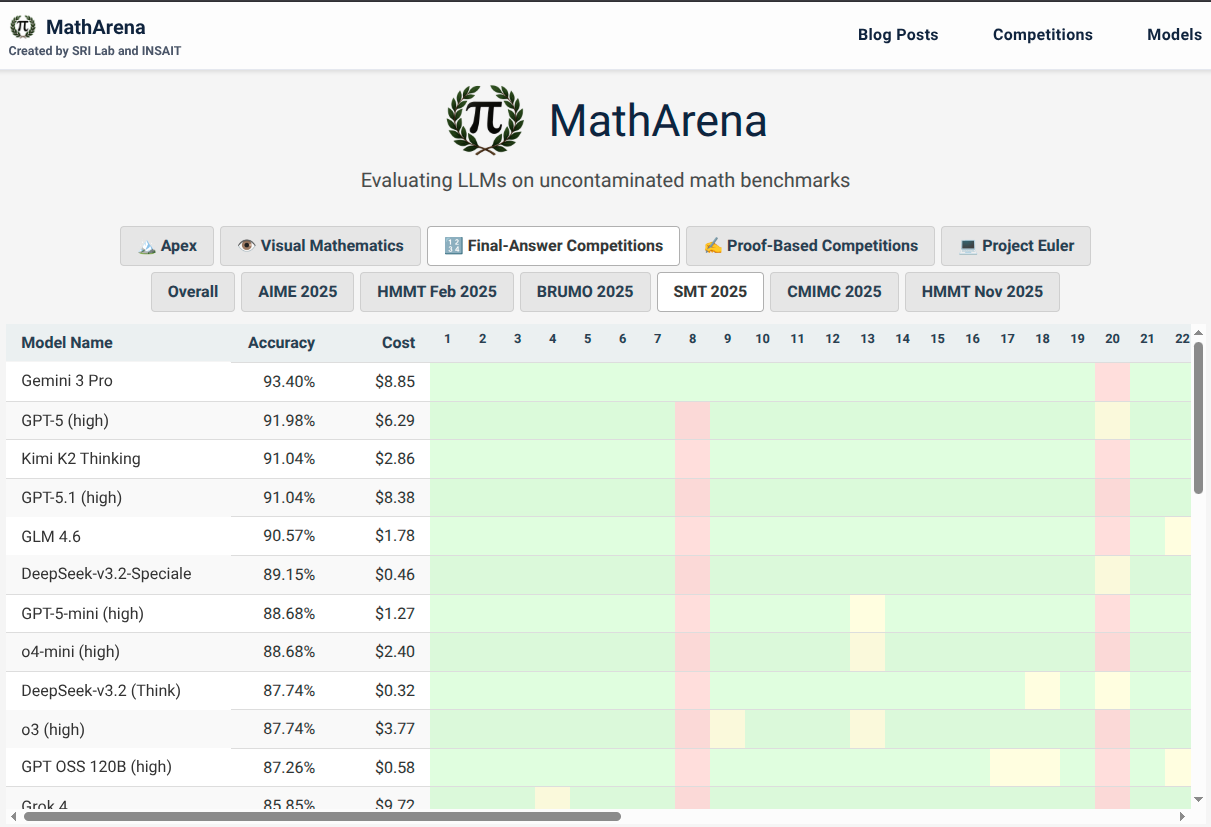
MathArena provides a contamination-free benchmark platform that rigorously evaluates how well Large Language Models handle mathematical reasoning and proof-writing. By using newly released competition problems, it ensures scores reflect genuine understanding rather than memorized solutions, so it’s essential for researchers tracking LLM progress in quantitative domains.
Fresh Math Problems to Prevent Benchmark Memorization
Many older benchmarks suffer from data leakage, where models might’ve encountered evaluation problems during their training. MathArena tackles this by exclusively using newly released problems from recurring math competitions and research-level tasks. That guarantees LLMs are tested on unseen data, so you’re getting a more accurate measure of their true reasoning abilities and preventing inflated performance scores due to memorization.
Competition-Style Problems Scored on Accuracy and Proof Quality
MathArena assesses LLMs on two primary types of tasks:
- Final-Answer Tasks: These require models to produce numerical or symbolic solutions. Scoring involves automated parsing using Sympy, with secondary judgment from an LLM (Gemini-2.5-Flash) and manual review for any discrepancies.
- Proof-Writing Tasks: These demand multi-step, natural-language proofs, including formal proof generation in Lean. Expert human evaluators, with two assigned per proof, grade these tasks using established contest rubrics. It’s rigorous and transparent — you’re getting reliable results and reproducibility.
Math Researchers, LLM Developers, and Competition Enthusiasts
The platform’s mainly for researchers, data scientists, and software engineers focused on developing and evaluating LLMs. Product managers and marketing analysts also use MathArena to track and understand advancements in AI capabilities. Specific use cases include:
- Benchmarking new LLMs against established math competitions.
- Assessing model performance on novel mathematical problems.
- Analyzing LLM reasoning on complex tasks.
- Comparing various AI models’ mathematical proficiency.
Automated Grading, LaTeX Output, and Public Leaderboards
MathArena supports evaluations for problems requiring single numeric/symbolic solutions and natural-language proofs, alongside formal proof generation in Lean. It integrates with a wide array of LLMs from major providers like OpenAI (GPT series), Google (Gemini series), Anthropic (Claude), and DeepSeek, typically via their public APIs. Model generations are capped at 64k tokens per problem to manage computational resources.
Top Models Still Fail on Multi-Step Proof Construction
Despite its advanced evaluation methods, MathArena highlights several significant challenges for current LLMs:
- Scalability of Proof Evaluation: The reliance on human grading for proofs is labor-intensive and not easily scalable, so you’re not easily expanding of proof-based benchmarks.
- LLM Proof Struggles: Even top LLMs demonstrate significant difficulty with rigorous proof generation, achieving less than 40% accuracy on demanding competitions such as IMO 2025 and USAMO 2025.
- Benchmark Size Constraints: The limited number of sufficiently challenging annual competitions means the benchmark size can be relatively small, leading to wider confidence intervals. Answer-based competitions may also reach saturation by 2026.
- Bluffing Behavior: LLMs sometimes produce incorrect proofs for false mathematical statements rather than identifying flaws or abstaining. That "bluffing" raises concerns about their reliability in critical mathematical applications.
- Verbosity: Some models generate overly verbose proofs, impacting conciseness and clarity.
Free Web Platform with Regular Competition Cycles
MathArena is an open-source and free platform. It publishes an evolving leaderboard that showcases model scores and confidence intervals, providing a public resource for tracking LLM progress in mathematical reasoning. You can find more information and access the platform at https://matharena.ai/.