
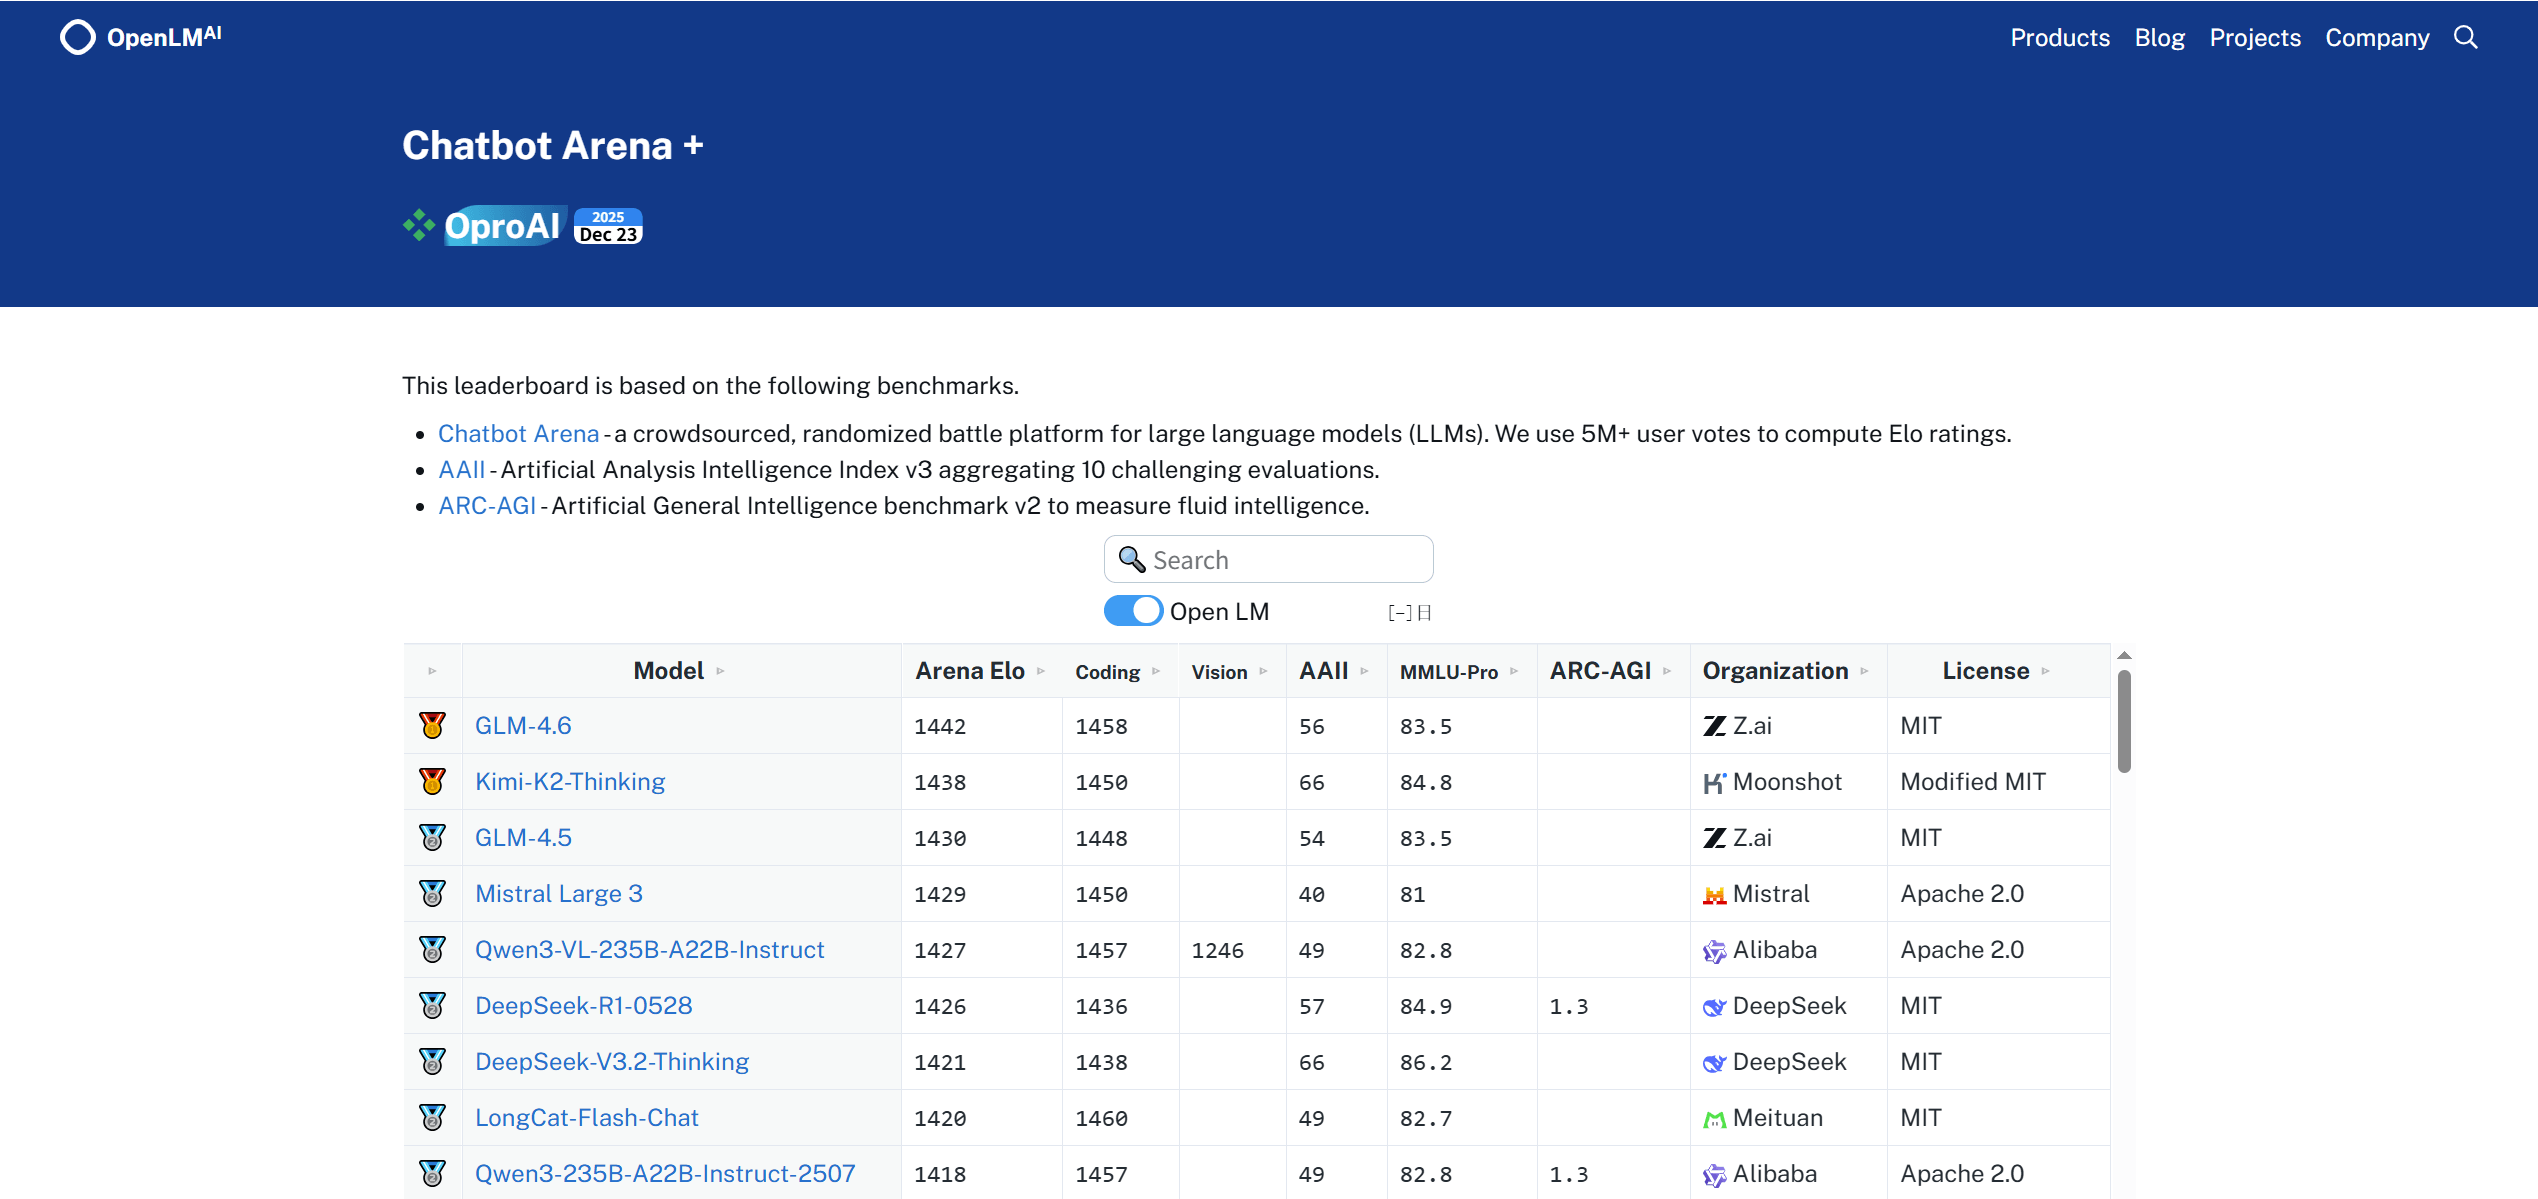
OpenLM Arena provides a dynamic platform for evaluating and comparing a wide array of AI models, from Large Language Models (LLMs) to image and video generation tools. It addresses the challenge of understanding real-world AI performance by leveraging crowdsourced data and established benchmarks, offering a continuously updated view of the AI field.
Blind A/B Testing with Human Preference Votes
At its core, OpenLM Arena operates on a crowdsourced "battle" system. Users submit a prompt and receive responses from two anonymous AI models. They then vote for their preferred response, or indicate a tie or if both are unsatisfactory. These votes, alongside data from benchmarks like AAII, ARC-AGI, MMLU, and Arena-Hard-Auto, feed into an Elo rating system, similar to chess, to generate real-time leaderboards. This approach provides a dynamic, human-centric evaluation of AI capabilities. It additionally allows direct interaction with individual models.
Model Developers, AI Engineers, and Researchers
This platform primarily serves AI and tech industry professionals, researchers, developers, and data analysts. It’s a valuable resource for anyone needing to identify top-performing AI models, conduct user preference testing, or access current leaderboards for both open-source and proprietary AI solutions. Users can determine which LLM best suits specific real-world tasks.
2M+ Human Votes, ELO Rating System, 100+ Models
OpenLM Arena evaluates a diverse range of AI models, including text LLMs, image generation models, vision LLMs, and web development models. The pairwise comparison mechanism keeps model identities hidden until after a vote is cast. The Elo rating system is built on millions of human votes; over 6 million votes have contributed to these ratings. The platform integrates various benchmarks, including the crowdsourced Chatbot Arena, MMLU, and Arena-Hard-Auto, with SWE-bench+ and International Olympiad in Informatics (IOI) also mentioned for specific evaluations. As of January 2024, it had accumulated over 240,000 votes from approximately 90,000 users across more than 100 languages. The crowdsourced data is considered to reflect real-world usage, with diverse and challenging prompts. Automated evaluation methods like Auto-Arena have shown a 92.14% correlation with human preferences.
Captures Subjective Quality Metrics Beyond Benchmark Scores
OpenLM Arena excels in providing "in-the-wild" evaluations based on human preference, a critical aspect often missed by traditional, static benchmarks. These traditional benchmarks rely on fixed datasets and can quickly become outdated. OpenLM Arena’s dynamic, continuously updated leaderboards and real-time user feedback offer a more current and relevant assessment of AI model performance. The crowdsourced nature ensures a diverse range of user prompts, accurately reflecting real-world applications and use cases across numerous languages. It provides a unified and interactive platform for comparing both proprietary and open-source models, allowing users to directly engage with and assess practical performance beyond numerical scores.
Vote Quality Varies, Popular Models Get More Exposure
While highly valuable, OpenLM Arena’s evaluation results may lean towards the preferences of tech enthusiasts and researchers, potentially not fully representing general user preferences. The subjective nature of human evaluation can also make it challenging to precisely differentiate between models with very close performance. Concerns have been raised regarding potential biases, such as unfair sampling rates for proprietary models, a lack of transparency in proprietary model testing, and the disproportionate deprecation of open-source models. There are also criticisms that commercial vendors might submit numerous models and then selectively publish only the highest-scoring ones, potentially incentivizing "gaming the system." Additionally, while free, users contribute their data (prompts and preferences), which is used for model training. When LLMs are used as judges in some benchmarks (e.g., Arena-Hard), issues with consistent numerical scoring can sometimes lead to inflated scores.
Free Web Platform, API for Dataset Access
OpenLM Arena is free to use. The platform benefits from user engagement by collecting preference data (prompts and votes), which is then utilized for post-training and improving AI models through reinforcement learning. You can explore the platform at OpenLM Arena.