
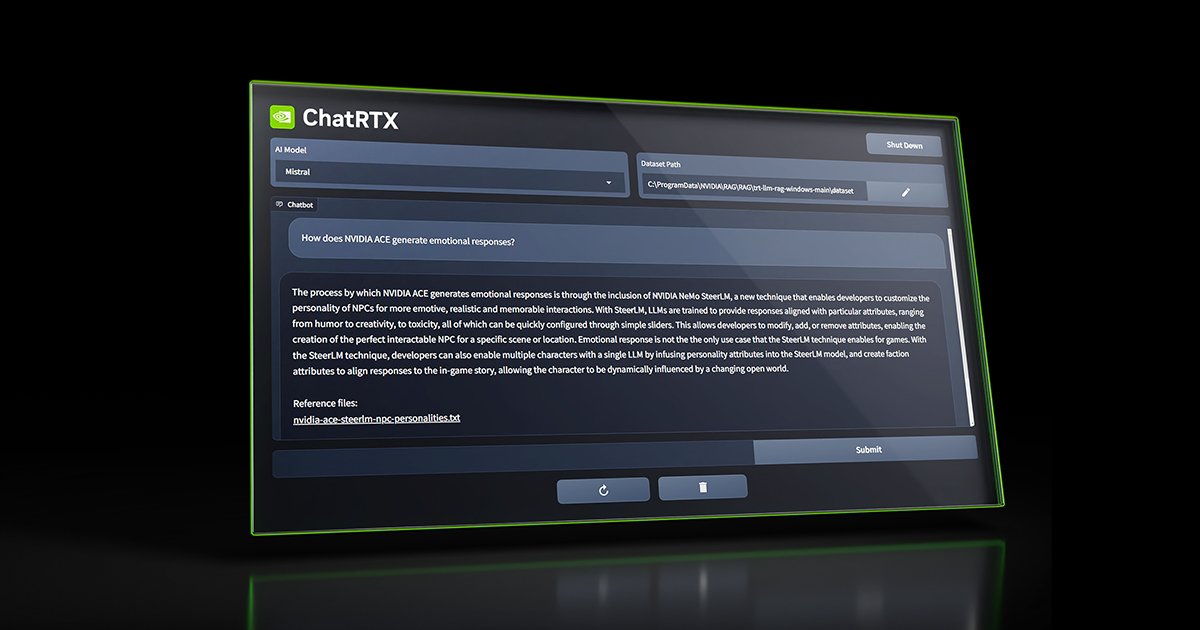
Interacting with personal data using a custom AI chatbot, all from the privacy of your own computer, is the core promise of NVIDIA ChatRTX. This tool allows users to query their local documents, notes, and images, receiving contextually relevant answers without needing an internet connection.
NVIDIA-Powered Local RAG for Document Q&A
ChatRTX creates a personalized chatbot that can summarize and find information within your local files. It uses retrieval-augmented generation (RAG) to connect large language models (LLMs) to your data during inference, enriching prompts with specific context from your documents. This process enhances the accuracy of the LLM’s predictions. The tool supports various AI models, including Mistral, Llama 2, Google’s Gemma, and ChatGLM3. It can also interact with image data using OpenAI’s CLIP and process voice queries via Whisper speech recognition.
Enterprise Users, Privacy-Sensitive Teams, and Offline Workers
This tool targets gamers, creators, developers, and anyone with an NVIDIA RTX GPU who wants to use AI for their local data. It’s particularly useful for quickly finding information in personal notes, summarizing content, or interacting with local image collections without complex metadata. Users who prioritize data privacy, require offline operation, or manage large local file libraries will find ChatRTX beneficial.
TensorRT-LLM Backend, RTX 30/40 Series GPU Required
ChatRTX runs locally on Windows PCs equipped with NVIDIA RTX 30 or 40 series GPUs (or newer, like RTX 50 series) that have at least 8GB of VRAM. It requires Windows 11 (or Windows 10) and 16GB of system RAM. The application supports various file types, including .txt, .pdf, .doc/.docx, .xml, .png, .jpg, and .bmp. It integrates NVIDIA TensorRT-LLM software and RTX acceleration, utilizing Tensor Cores for faster inference and reduced latency. The backend APIs also allow developers to integrate advanced AI inference and RAG features into their own applications.
Zero Data Leaves Your Machine, No Internet Required
ChatRTX excels at providing a private and secure way to interact with personal data. All processing occurs directly on the user’s device, eliminating the need to share data with third-party cloud services. This local operation ensures data privacy and delivers fast, contextually relevant answers from personal files. It simplifies the process of running LLMs on consumer GPUs, making AI interaction with personal content more accessible than complex open-source alternatives.
NVIDIA RTX GPU Mandatory, Windows Only, Setup Complexity
ChatRTX has significant hardware requirements — it demands advanced RTX GPUs:
Free Download from NVIDIA, ~6GB VRAM Minimum
ChatRTX is available as a free download from the official NVIDIA website: https://www.nvidia.com/en-us/ai-on-rtx/chatrtx/