

Together.ai offers an "AI Acceleration Cloud" that provides developers and researchers with high-performance infrastructure to build, train, fine-tune, and deploy open-source generative AI models at scale. Its platform combines serverless endpoints, dedicated GPU clusters, and serverless fine-tuning.
Developers and Enterprises Scaling AI on Open-Source Models
Together.ai primarily serves AI researchers, developers, and companies with dedicated AI/ML teams. These groups use the platform to build AI applications from scratch, customize models, or access raw GPU power. Specific use cases include developing chatbots, coding assistants, and search agents, as well as fine-tuning models with proprietary datasets. It also supports enterprise AI workloads such as document summarization, data classification, and retrieval-augmented generation (RAG) pipelines. While it can facilitate the development of customer service automation or marketing tools, it’s not a ready-to-use solution for non-technical business users.
200+ Open-Source Models with Serverless Endpoints
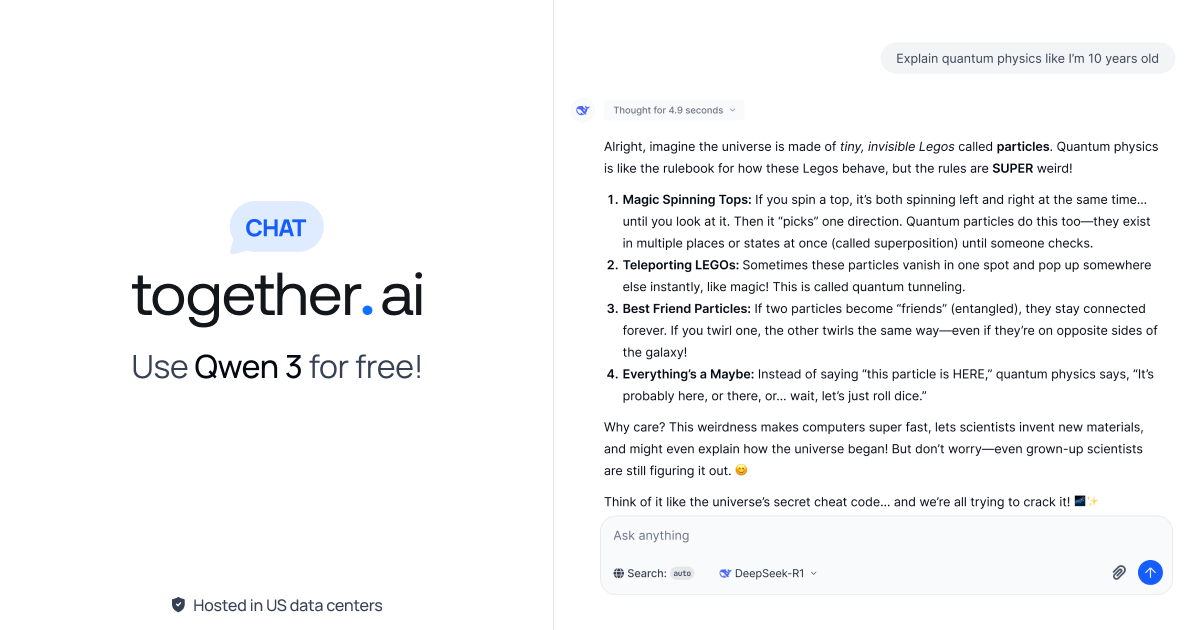
The platform offers a full suite of functionalities for working with generative AI. It hosts a library of over 200 open-source models, encompassing large language models (LLMs), image generation models, and multimodal systems. Developers can utilize high-performance GPU infrastructure and APIs for both serverless inference (running models) and fine-tuning (customizing models with specific data). The chat.together.ai interface provides a direct way to interact with certain models, such as DeepSeek V3.1 and Qwen 3, for conversational AI tasks.
Serverless Inference, Dedicated Endpoints, and Fine-Tuning
Together.ai’s infrastructure relies on high-performance NVIDIA GPUs (H100, A100, H200, GB200) with advanced interconnects. The platform is optimized for high-speed inference, claiming up to 4x faster performance than traditional deployments and speeds exceeding 400 tokens/second, achieved through techniques like FlashAttention and Flash-Decoding. It offers OpenAI-compatible APIs, streamlining integration and migration for developers. The platform supports extensive integrations with frameworks like Hugging Face, Vercel AI SDK, LangChain, LlamaIndex, CrewAI, and AutoGen. The chat completion API allows granular control over parameters such as max_tokens, temperature, top_p, top_k, and stop sequences.
Pay-per-Token Pricing Starting from $0.10/Million
Together.ai operates on a consumption-based pricing model, where users pay per token for serverless inference, per minute for dedicated endpoints, per megapixel for image generation, and per second for video/audio processing. There are no subscription tiers, setup fees, or minimum commitments for serverless inference. New users receive $25 in free credits to experiment. Pricing is often asymmetric, with input tokens typically costing less than output tokens. The chat.together.ai interface is advertised as "Free DeepSeek V3.1 & Qwen 3 Chat AI," suggesting free usage for these specific models through the chat interface, likely utilizing the free credits or a basic free tier.
Rate Limits, Hallucination Risk, and Open-Source Model Gaps
Together.ai demands significant technical expertise — it isn’t designed for non-technical users:
- Requires developer skills to configure endpoints, manage API calls, and handle model deployment.
- Pay-per-token pricing can lead to unpredictable costs, especially during development and testing phases.
- No visual interface for model management — everything is done through API calls and CLI tools.